Vidu Q2

AI Image Editing Model

Image $$$$ · 10¢

ShengShu Technology's text-to-image and reference-to-image model with support for character consistency and multi-reference image processing

Supported Modes
Text to Image Image Edit
Active

Details

Model ID
vidu-q2
Family
vidu
Released
September 2025
Max Input Images
3
Tags
image-generation text-to-image image-editing
// Get Started

Ready to integrate?

Access vidu-q2 via our unified API.

Create Account
Available at 1 provider

Starting from

$0.100 /image via fal.ai

Prices shown are in USD

Full pricing details

Providers & Pricing (1)

Vidu Q2 is available exclusively through fal.ai, starting at $0.1/image.

fal.ai
Text to Image
fal/vidu-q2
Provider Model ID: fal-ai/vidu/q2/text-to-image
$0.100 /image

Vidu Q2 API OpenAI-compatible

Integrate Vidu Q2 into your workflow using Lumenfall's OpenAI-compatible API to perform advanced text-to-image generation and complex image editing through a single endpoint.

Base URL
https://api.lumenfall.ai/openai/v1
Model
vidu-q2

Code Examples

Text to Image

/v1/images/generations
curl -X POST \
  https://api.lumenfall.ai/openai/v1/images/generations \
  -H "Authorization: Bearer $LUMENFALL_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "vidu-q2",
    "prompt": "",
    "size": "1024x1024"
  }'
# Response:
# { "created": 1234567890, "data": [{ "url": "https://...", "revised_prompt": "..." }] }

Parameter Reference

Required Supported Not available

Core Parameters

Parameter Type Description Modes
prompt string Required. Text prompt for image generation
T2I Edit
seed integer Random seed for reproducibility
T2I Edit

Size & Layout

Parameter Type Description Modes
size string Image dimensions as WxH pixels (e.g. "1024x1024") or aspect ratio (e.g. "16:9")
1365x768 768x1365 1024x1024
WxH determines both shape and scale (aspect_ratio and resolution are ignored when size is provided). W:H format is equivalent to aspect_ratio.
T2I Edit
aspect_ratio string Aspect ratio of the output image (e.g. "16:9", "1:1")
9:16 1:1 16:9
Controls shape independently of scale. Use with resolution to control both. If size is also provided, size takes precedence. Any ratio is accepted and mapped to the nearest supported value.
T2I Edit
resolution string Output resolution tier (e.g. "1K", "4K")
1K
Controls scale independently of shape. Higher tiers produce larger images and cost more. If size is also provided, size takes precedence for scale. Any tier is accepted and mapped to the nearest supported value.
T2I Edit
1K 3 sizes
Output size aspect_ratio + resolution
1024 × 1024 "1024x1024" or "1:1" + "1K"
768 × 1365 "768x1365" or "9:16" + "1K"
1365 × 768 "1365x768" or "16:9" + "1K"

How these parameters work

size

Exact pixel dimensions

"1920x1080"
aspect_ratio

Shape only, default scale

"16:9"
resolution

Scale tier, preserves shape

"1K"

Priority when combined

size aspect_ratio + resolution aspect_ratio resolution

size is most specific and always wins. aspect_ratio and resolution control shape and scale independently.

How matching works

Shape matching – we pick the closest supported ratio. Ask for 7:1 on a model with 4:1 and 8:1, you get 8:1.
Scale matching – providers use different tier formats: K tiers (0.5K 1K 2K 4K) or megapixel tiers (0.25 1). If the exact tier isn't available, you get the nearest one.
Dimension clamping – if a model has pixel limits, we clamp dimensions to fit and keep the aspect ratio intact.

Media Inputs

Parameter Type Description Modes

Output & Format

Parameter Type Description Modes
response_format string How to return the image
url b64_json
Default: "url"
T2I Edit
output_format string Output image format
png jpeg gif webp avif
Gateway converts to requested format if provider doesn't support it natively.
T2I Edit
output_compression integer Compression level for lossy formats (JPEG, WebP, AVIF)
T2I Edit
n integer Number of images to generate
Default: 1
Gateway generates multiple images in parallel even if provider only supports 1.
T2I Edit

Parameter Normalization

How we handle parameters across different providers

Not every provider speaks the same language. When you send a parameter, we handle it in one of four ways depending on what the model supports:

Behavior What happens Example
passthrough Sent as-is to the provider style, quality
renamed Same value, mapped to the field name the provider expects prompt
converted Transformed to the provider's native format size
emulated Works even if the provider has no concept of it n, response_format

Parameters we don't recognize pass straight through to the upstream API, so provider-specific options still work.

Vidu Q2 Benchmarks

Vidu Q2 is ranked #28 in Image Editing with an Elo of 1155 and #40 in Text-to-Image with an Elo of 1215 on the Lumenfall Arena, where real users pick the better image in blind comparisons. These rankings are based on 8 blind-vote competitions.

Lumenfall Arena
#28
Image Editing
1155 Elo
Lumenfall Arena
#40
Text-to-Image
1215 Elo

Text-to-Image Landscape

Competition Results

Text-to-Image

Prompt Adherence

View leaderboard
Text-to-Image
Prompt

“Photorealistic scene inside a yellow New York taxi at night. A capybara is driving, wearing a yellow taxi driver cap and a dark jacket. It has a calm, professional expression and both front paws on the steering wheel. In the back seat sits a human businesswoman in a coat, looking at her phone with a completely normal, bored expression (as if this is just another normal ride). Through the windows you can see the streets of Manhattan at night with blurred lights. Realistic taxi interior, photorealistic, detailed fur and fabric, 35mm lens, night lighting with reflections, shallow depth of field.”

#32
Geometric Composition
70 models
Text-to-Image
Prompt

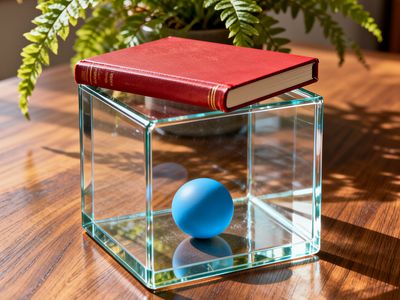
“A glass cube on a wooden table. Inside the cube is a small blue sphere. On top of the cube sits a red book. A green plant is behind the cube, partially visible through the glass. Soft window light from the left.”

Text-to-Image
Prompt

“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”

Text-to-Image
Prompt

“Hyper-photorealistic scene of fluffy baby animals—a golden retriever puppy, tabby kitten, baby bunny, and red fox kit—with big expressive eyes and ultra-detailed soft fur, playfully chasing butterflies and tumbling together in a lush wildflower meadow, warm golden sunrise light with god rays and dew sparkles, joyful wholesome vibe, 8K masterpiece.”

Text-to-Image
Prompt

“Create a clean, modern vector infographic poster about the Apollo 11 mission. NASA-inspired palette (navy, white, muted red, light gray). Flat-vector style, crisp lines, consistent iconography, subtle gradients only. Steps (stop at landing): 1. Launch (Saturn Vicon) 2. Earth Orbit (Earth + orbit ring icon) 3. Translunar (trajectory arc icon) 4. Lunar Orbit (Moon + orbit ring icon) 5. Descent (lunar module descending icon) 6. Landing (lunar module on the surface icon) Small supporting elements (minimal text): • Crew strip: three silhouette icons with only last names: Armstrong, Aldrin, Collins. • Landing site marker: Moon pin labeled "Tranquility" only. Layout constraints: generous margins, large readable labels, clean background with subtle stars. Vector-only, print-poster look, high resolution.”

Text-to-Image

Aesthetics

View leaderboard
Text-to-Image
Prompt

“Photorealistic scene inside a yellow New York taxi at night. A capybara is driving, wearing a yellow taxi driver cap and a dark jacket. It has a calm, professional expression and both front paws on the steering wheel. In the back seat sits a human businesswoman in a coat, looking at her phone with a completely normal, bored expression (as if this is just another normal ride). Through the windows you can see the streets of Manhattan at night with blurred lights. Realistic taxi interior, photorealistic, detailed fur and fabric, 35mm lens, night lighting with reflections, shallow depth of field.”

#32
Geometric Composition
70 models
Text-to-Image
Prompt

“A glass cube on a wooden table. Inside the cube is a small blue sphere. On top of the cube sits a red book. A green plant is behind the cube, partially visible through the glass. Soft window light from the left.”

Text-to-Image
Prompt

“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”

#30
The Halloween Invitation
70 models
Text-to-Image
Prompt

“Vintage gothic Halloween party invitation. Dark parchment poster, spooky border with webs and thorns, central glowing jack-o-lantern, bats, twisted trees, moody night sky. Add elegant gothic title text saying "Halloween Party Invitation", a small scroll banner saying "You are invited to a night of frights", and event details at the bottom: Date: 30.10.2026 Time: 7pm Location: The Arches, NYC Spooky but polished, cinematic lighting, square format.”

Text-to-Image
Prompt

“Hyper-photorealistic scene of fluffy baby animals—a golden retriever puppy, tabby kitten, baby bunny, and red fox kit—with big expressive eyes and ultra-detailed soft fur, playfully chasing butterflies and tumbling together in a lush wildflower meadow, warm golden sunrise light with god rays and dew sparkles, joyful wholesome vibe, 8K masterpiece.”

#56
Fantasy Warrior
71 models
Text-to-Image
Prompt

“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”

#69
Vintage Cafe Logo
70 models
Text-to-Image
Prompt

“Vintage minimalist restaurant logo for "Caffè Florian", retro cloche dome with steam and "Est. 1720" banner, classic typography, warm brown and cream tones, subtle texture on light background, vector emblem style.”

Text-to-Image

Creativity

View leaderboard
Text-to-Image
Prompt

“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”

#30
The Halloween Invitation
70 models
Text-to-Image
Prompt

“Vintage gothic Halloween party invitation. Dark parchment poster, spooky border with webs and thorns, central glowing jack-o-lantern, bats, twisted trees, moody night sky. Add elegant gothic title text saying "Halloween Party Invitation", a small scroll banner saying "You are invited to a night of frights", and event details at the bottom: Date: 30.10.2026 Time: 7pm Location: The Arches, NYC Spooky but polished, cinematic lighting, square format.”

#56
Fantasy Warrior
71 models
Text-to-Image
Prompt

“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”

Text-to-Image
Prompt

“Create a clean, modern vector infographic poster about the Apollo 11 mission. NASA-inspired palette (navy, white, muted red, light gray). Flat-vector style, crisp lines, consistent iconography, subtle gradients only. Steps (stop at landing): 1. Launch (Saturn Vicon) 2. Earth Orbit (Earth + orbit ring icon) 3. Translunar (trajectory arc icon) 4. Lunar Orbit (Moon + orbit ring icon) 5. Descent (lunar module descending icon) 6. Landing (lunar module on the surface icon) Small supporting elements (minimal text): • Crew strip: three silhouette icons with only last names: Armstrong, Aldrin, Collins. • Landing site marker: Moon pin labeled "Tranquility" only. Layout constraints: generous margins, large readable labels, clean background with subtle stars. Vector-only, print-poster look, high resolution.”

#69
Vintage Cafe Logo
70 models
Text-to-Image
Prompt

“Vintage minimalist restaurant logo for "Caffè Florian", retro cloche dome with steam and "Est. 1720" banner, classic typography, warm brown and cream tones, subtle texture on light background, vector emblem style.”

Text-to-Image

Photorealism

View leaderboard
Text-to-Image
Prompt

“Photorealistic scene inside a yellow New York taxi at night. A capybara is driving, wearing a yellow taxi driver cap and a dark jacket. It has a calm, professional expression and both front paws on the steering wheel. In the back seat sits a human businesswoman in a coat, looking at her phone with a completely normal, bored expression (as if this is just another normal ride). Through the windows you can see the streets of Manhattan at night with blurred lights. Realistic taxi interior, photorealistic, detailed fur and fabric, 35mm lens, night lighting with reflections, shallow depth of field.”

#32
Geometric Composition
70 models
Text-to-Image
Prompt

“A glass cube on a wooden table. Inside the cube is a small blue sphere. On top of the cube sits a red book. A green plant is behind the cube, partially visible through the glass. Soft window light from the left.”

Text-to-Image
Prompt

“Hyper-photorealistic scene of fluffy baby animals—a golden retriever puppy, tabby kitten, baby bunny, and red fox kit—with big expressive eyes and ultra-detailed soft fur, playfully chasing butterflies and tumbling together in a lush wildflower meadow, warm golden sunrise light with god rays and dew sparkles, joyful wholesome vibe, 8K masterpiece.”

#56
Fantasy Warrior
71 models
Text-to-Image
Prompt

“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”

Text-to-Image

Text Rendering

View leaderboard
Text-to-Image
Prompt

“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”

#30
The Halloween Invitation
70 models
Text-to-Image
Prompt

“Vintage gothic Halloween party invitation. Dark parchment poster, spooky border with webs and thorns, central glowing jack-o-lantern, bats, twisted trees, moody night sky. Add elegant gothic title text saying "Halloween Party Invitation", a small scroll banner saying "You are invited to a night of frights", and event details at the bottom: Date: 30.10.2026 Time: 7pm Location: The Arches, NYC Spooky but polished, cinematic lighting, square format.”

Text-to-Image
Prompt

“Create a clean, modern vector infographic poster about the Apollo 11 mission. NASA-inspired palette (navy, white, muted red, light gray). Flat-vector style, crisp lines, consistent iconography, subtle gradients only. Steps (stop at landing): 1. Launch (Saturn Vicon) 2. Earth Orbit (Earth + orbit ring icon) 3. Translunar (trajectory arc icon) 4. Lunar Orbit (Moon + orbit ring icon) 5. Descent (lunar module descending icon) 6. Landing (lunar module on the surface icon) Small supporting elements (minimal text): • Crew strip: three silhouette icons with only last names: Armstrong, Aldrin, Collins. • Landing site marker: Moon pin labeled "Tranquility" only. Layout constraints: generous margins, large readable labels, clean background with subtle stars. Vector-only, print-poster look, high resolution.”

#69
Vintage Cafe Logo
70 models
Text-to-Image
Prompt

“Vintage minimalist restaurant logo for "Caffè Florian", retro cloche dome with steam and "Est. 1720" banner, classic typography, warm brown and cream tones, subtle texture on light background, vector emblem style.”

Text-to-Image

Art

View leaderboard
#30
The Halloween Invitation
70 models
Text-to-Image
Prompt

“Vintage gothic Halloween party invitation. Dark parchment poster, spooky border with webs and thorns, central glowing jack-o-lantern, bats, twisted trees, moody night sky. Add elegant gothic title text saying "Halloween Party Invitation", a small scroll banner saying "You are invited to a night of frights", and event details at the bottom: Date: 30.10.2026 Time: 7pm Location: The Arches, NYC Spooky but polished, cinematic lighting, square format.”

Text-to-Image

Portraits

View leaderboard
#56
Fantasy Warrior
71 models
Text-to-Image
Prompt

“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”

Text-to-Image

Cartoon, Anime & Fantasy

View leaderboard
#56
Fantasy Warrior
71 models
Text-to-Image
Prompt

“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”

Text-to-Image

Product, Branding & Commercial

View leaderboard
#30
The Halloween Invitation
70 models
Text-to-Image
Prompt

“Vintage gothic Halloween party invitation. Dark parchment poster, spooky border with webs and thorns, central glowing jack-o-lantern, bats, twisted trees, moody night sky. Add elegant gothic title text saying "Halloween Party Invitation", a small scroll banner saying "You are invited to a night of frights", and event details at the bottom: Date: 30.10.2026 Time: 7pm Location: The Arches, NYC Spooky but polished, cinematic lighting, square format.”

Text-to-Image
Prompt

“Create a clean, modern vector infographic poster about the Apollo 11 mission. NASA-inspired palette (navy, white, muted red, light gray). Flat-vector style, crisp lines, consistent iconography, subtle gradients only. Steps (stop at landing): 1. Launch (Saturn Vicon) 2. Earth Orbit (Earth + orbit ring icon) 3. Translunar (trajectory arc icon) 4. Lunar Orbit (Moon + orbit ring icon) 5. Descent (lunar module descending icon) 6. Landing (lunar module on the surface icon) Small supporting elements (minimal text): • Crew strip: three silhouette icons with only last names: Armstrong, Aldrin, Collins. • Landing site marker: Moon pin labeled "Tranquility" only. Layout constraints: generous margins, large readable labels, clean background with subtle stars. Vector-only, print-poster look, high resolution.”

#69
Vintage Cafe Logo
70 models
Text-to-Image
Prompt

“Vintage minimalist restaurant logo for "Caffè Florian", retro cloche dome with steam and "Est. 1720" banner, classic typography, warm brown and cream tones, subtle texture on light background, vector emblem style.”

Text-to-Image

3D Imaging & Modeling

View leaderboard
#32
Geometric Composition
70 models
Text-to-Image
Prompt

“A glass cube on a wooden table. Inside the cube is a small blue sphere. On top of the cube sits a red book. A green plant is behind the cube, partially visible through the glass. Soft window light from the left.”

Text-to-Image
Prompt

“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”

Help rank Vidu Q2 Pick the better image in blind matchups. Results update rankings in real time.
Start Voting

Vidu Q2 is best for

See all Use Cases

Vidu Q2 FAQ

How much does Vidu Q2 cost?

Vidu Q2 starts at $0.1 per image through Lumenfall. Pricing varies by provider. Lumenfall does not add any markup to provider pricing.

How do I use Vidu Q2 via API?

You can use Vidu Q2 through Lumenfall's OpenAI-compatible API. Send requests to the unified endpoint with model ID "vidu-q2". Code examples are available in Python, JavaScript, and cURL.

Which providers offer Vidu Q2?

Vidu Q2 is available through fal.ai on Lumenfall. Lumenfall automatically routes requests to the best available provider.

Overview

Vidu Q2 is a specialized image generation model developed by ShengShu Technology that prioritizes structural control and character consistency. Unlike standard text-to-image models that often struggle to maintain identity across multiple generations, Vidu Q2 is designed to process multiple reference images to anchor the visual features of a subject. This makes it a functional tool for creators who need to place the same character or object into varying environments and poses without losing visual fidelity.

Strengths

  • Character Consistency: The model excels at preserving the identity, facial features, and attire of a subject when provided with reference images, reducing the “hallucination” of new traits between frames or shots.
  • Multi-Reference Processing: It can ingest and synthesize information from more than one reference image simultaneously, allowing for better 360-degree understanding of a subject’s geometry and textures.
  • Structural Adherence: Vidu Q2 demonstrates high accuracy in following compositional instructions, ensuring that the spatial relationship between the subject and the background remains coherent.
  • Prompt Alignment: It maintains a strong correlation between complex text prompts and the resulting visual elements, even when constrained by specific image references.

Limitations

  • Style Rigidity: Because the model focuses heavily on consistency, it may sometimes inherit unwanted lighting or stylistic artifacts from the reference images, making it difficult to completely pivot to a drastically different art style without significant prompting effort.
  • Attribute Bleeding: When using multiple reference images with conflicting details (e.g., a character wearing different hats in two photos), the model may intermittently blend these features in unexpected ways.
  • Lower Creative Variance: Users seeking “happy accidents” or high stylistic diversity may find the model’s output overly constrained compared to more generalized diffusion models like Stable Diffusion XL or Flux.

Technical Background

Vidu Q2 is part of the Vidu family of generative models, utilizing a transformer-based architecture optimized for multimodal inputs. The model’s key technical differentiator is its specialized attention mechanism that gives weighted priority to visual tokens extracted from reference images. This training approach allows the model to treat reference images as “hard constraints” rather than mere stylistic suggestions, ensuring the generated output remains grounded in the provided visual data.

Best For

Vidu Q2 is best suited for storyboarding, character design, and brand-consistent marketing campaigns where maintaining a singular “hero” subject is critical. It is an effective choice for game developers and concept artists who need to visualize a character in multiple scenarios or lighting conditions.

Vidu Q2 is available to explore through the Lumenfall playground and can be integrated into production workflows via the Lumenfall unified API, providing a consistent interface for high-fidelity character generation.
Try Vidu Q2 in Playground

Generate images with custom prompts — no API key needed.

Open Playground