Text-to-Image
Prompt
“Horse riding astronaut in space — horse on top, not vice versa. Surreal, highly detailed, cinematic.”
AI Image Editing Model
Black Forest Labs' premium multimodal flow transformer with greatly improved prompt adherence and typography generation for in-context image generation and editing without compromise on speed


flux.1-kontext-max
Starting from
Prices shown are in USD
See all providersFLUX.1 Kontext [max] is available from 4 providers, with per-image pricing starting at $0.08 through fal.ai.
fal/flux.1-kontext-max
fal/flux.1-kontext-max-edit
fireworks/flux.1-kontext-max
replicate/flux.1-kontext-max
Integrate FLUX.1 Kontext [max] via the Lumenfall API to perform high-speed text-to-image generation and complex image editing through a single OpenAI-compatible endpoint.
https://api.lumenfall.ai/openai/v1
flux.1-kontext-max
curl -X POST \ https://api.lumenfall.ai/openai/v1/images/generations \ -H "Authorization: Bearer $LUMENFALL_API_KEY" \ -H "Content-Type: application/json" \ -d '{ "model": "flux.1-kontext-max", "prompt": "", "size": "1024x1024" }'# Response:# { "created": 1234567890, "data": [{ "url": "https://...", "revised_prompt": "..." }] }import OpenAI from 'openai';const client = new OpenAI({ apiKey: 'YOUR_API_KEY', baseURL: 'https://api.lumenfall.ai/openai/v1'});const response = await client.images.generate({ model: 'flux.1-kontext-max', prompt: '', size: '1024x1024'});// { created: 1234567890, data: [{ url: "https://...", revised_prompt: "..." }] }console.log(response.data[0].url);from openai import OpenAIclient = OpenAI( api_key="YOUR_API_KEY", base_url="https://api.lumenfall.ai/openai/v1")response = client.images.generate( model="flux.1-kontext-max", prompt="", size="1024x1024")# { created: 1234567890, data: [{ url: "https://...", revised_prompt: "..." }] }print(response.data[0].url)curl -X POST \ https://api.lumenfall.ai/openai/v1/images/edits \ -H "Authorization: Bearer $LUMENFALL_API_KEY" \ -F "model=flux.1-kontext-max" \ -F "[email protected]" \ -F "prompt=Add a starry night sky to this image" \ -F "size=1024x1024"# Response:# { "created": 1234567890, "data": [{ "url": "https://...", "revised_prompt": "..." }] }import OpenAI from 'openai';import fs from 'fs';const client = new OpenAI({ apiKey: 'YOUR_API_KEY', baseURL: 'https://api.lumenfall.ai/openai/v1'});const response = await client.images.edit({ model: 'flux.1-kontext-max', image: fs.createReadStream('source.png'), prompt: 'Add a starry night sky to this image', size: '1024x1024'});// { created: 1234567890, data: [{ url: "https://...", revised_prompt: "..." }] }console.log(response.data[0].url);from openai import OpenAIclient = OpenAI( api_key="YOUR_API_KEY", base_url="https://api.lumenfall.ai/openai/v1")response = client.images.edit( model="flux.1-kontext-max", image=open("source.png", "rb"), prompt="Add a starry night sky to this image", size="1024x1024")# { created: 1234567890, data: [{ url: "https://...", revised_prompt: "..." }] }print(response.data[0].url)| Parameter | Type | Description | Modes |
|---|---|---|---|
prompt
|
string | Required. Edit instruction for the image |
T2I
Edit
|
seed
|
integer | Random seed for reproducibility |
T2I
Edit
|
| Parameter | Type | Description | Modes |
|---|---|---|---|
size
|
string |
Image dimensions as WxH pixels (e.g. "1024x1024") or aspect ratio (e.g. "16:9")
WxH determines both shape and scale (aspect_ratio and resolution are ignored when size is provided). W:H format is equivalent to aspect_ratio.
|
T2I
Edit
|
aspect_ratio
|
string |
Aspect ratio of the output image (e.g. "16:9", "1:1")
Controls shape independently of scale. Use with resolution to control both. If size is also provided, size takes precedence. Any ratio is accepted and mapped to the nearest supported value.
|
T2I
Edit
|
resolution
|
string |
Output resolution tier (e.g. "1K", "4K")
auto
1K
Controls scale independently of shape. Higher tiers produce larger images and cost more. If size is also provided, size takes precedence for scale. Any tier is accepted and mapped to the nearest supported value.
|
T2I
Edit
|
| Output |
size
|
aspect_ratio
+
resolution
|
|
|---|---|---|---|
| Flexible | |||
| Auto | "auto" |
— | Model chooses optimal dimensions |
| Output |
size
|
aspect_ratio
+
resolution
|
|
|---|---|---|---|
| 1183 × 887 | "1183x887" |
or |
"4:3"
+
"1K"
|
| 916 × 1145 | "916x1145" |
or |
"4:5"
+
"1K"
|
| 1145 × 916 | "1145x916" |
or |
"5:4"
+
"1K"
|
| 1024 × 1024 | "1024x1024" |
or |
"1:1"
+
"1K"
|
| 887 × 1182 | "887x1182" |
or |
"3:4"
+
"1K"
|
| 724 × 1448 | "724x1448" |
or |
"1:2"
+
"1K"
|
| 1448 × 724 | "1448x724" |
or |
"2:1"
+
"1K"
|
| 836 × 1254 | "836x1254" |
or |
"2:3"
+
"1K"
|
| 1254 × 836 | "1254x836" |
or |
"3:2"
+
"1K"
|
| 768 × 1365 | "768x1365" |
or |
"9:16"
+
"1K"
|
| 1365 × 768 | "1365x768" |
or |
"16:9"
+
"1K"
|
| 670 × 1564 | "670x1564" |
or |
"9:21"
+
"1K"
|
| 1563 × 670 | "1563x670" |
or |
"21:9"
+
"1K"
|
size
Exact pixel dimensions
"1920x1080"
aspect_ratio
Shape only, default scale
"16:9"
resolution
Scale tier, preserves shape
"1K"
size is most specific and always wins. aspect_ratio and resolution control shape and scale independently.
7:1 on a model with
4:1 and 8:1,
you get 8:1.
0.5K 1K 2K 4K)
or megapixel tiers (0.25 1).
If the exact tier isn't available, you get the nearest one.
| Parameter | Type | Description | Modes |
|---|---|---|---|
image
|
file |
Required.
Input image(s) to edit
Supports PNG, JPEG, WebP.
Single image per request.
|
T2I
Edit
|
| Parameter | Type | Description | Modes |
|---|---|---|---|
response_format
|
string |
How to return the image
url
b64_json
Default:
"url" |
T2I
Edit
|
output_format
|
string |
Output image format
png
jpeg
gif
webp
avif
Gateway converts to requested format if provider doesn't support it natively.
|
T2I
Edit
|
output_compression
|
integer | Compression level for lossy formats (JPEG, WebP, AVIF) |
T2I
Edit
|
n
|
integer |
Number of images to generate
Default:
1Gateway generates multiple images in parallel even if provider only supports 1.
|
T2I
Edit
|
Provider-specific passthrough fields, available only when the request is routed to the listed provider.
| Parameter | Type | Description | Modes |
|---|---|---|---|
|
Universal
|
|||
cfg_scale
|
number | Classifier-free guidance scale — higher values stick more closely to the prompt |
T2I
Edit
|
prompt_enhancement
|
string |
Whether an LLM rewrites/expands the prompt before generation (off, on)
off
on
|
T2I
Edit
|
safety_tolerance
|
string |
The safety tolerance level for the generated image. 1 being the most strict and 5 being the most permissive.
1
2
3
4
5
6
|
T2I
Edit
|
|
fal
|
|||
sync_mode
|
boolean | If `True`, the media will be returned as a data URI and the output data won't be available in the request history. |
T2I
Edit
|
|
fireworks
|
|||
webhook_secret
|
["string", "null"] | Optional secret for webhook signature verification. |
T2I
Edit
|
webhook_url
|
["string", "null"] | URL to receive webhook notifications. |
T2I
Edit
|
How we handle parameters across different providers
Not every provider speaks the same language. When you send a parameter, we handle it in one of four ways depending on what the model supports:
| Behavior | What happens | Example |
|---|---|---|
passthrough |
Sent as-is to the provider | style, quality |
renamed |
Same value, mapped to the field name the provider expects | prompt |
converted |
Transformed to the provider's native format | size |
emulated |
Works even if the provider has no concept of it | n, response_format |
Parameters we don't recognize pass straight through to the upstream API, so provider-specific options still work.
FLUX.1 Kontext [max] is ranked #16 in Text-to-Image with an Elo of 1249 and #36 in Image Editing with an Elo of 1103 on the Lumenfall Arena, where real users pick the better image in blind comparisons. These rankings are based on 8 blind-vote competitions.
1 model without pricing omitted.
40 models waiting for enough speed data.
1 model without pricing omitted.
16 models waiting for enough speed data.
“Horse riding astronaut in space — horse on top, not vice versa. Surreal, highly detailed, cinematic.”
“Modern minimalist restaurant menu design, white background with colorful food photos in grid, sections for appetizers/pizza/mains, bold sans-serif fonts, vibrant accents, clean professional layout for casual dining.”
“Photorealistic scene inside a yellow New York taxi at night. A capybara is driving, wearing a yellow taxi driver cap and a dark jacket. It has a calm, professional expression and both front paws on the steering wheel. In the back seat sits a human businesswoman in a coat, looking at her phone with a completely normal, bored expression (as if this is just another normal ride). Through the windows you can see the streets of Manhattan at night with blurred lights. Realistic taxi interior, photorealistic, detailed fur and fabric, 35mm lens, night lighting with reflections, shallow depth of field.”
“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”
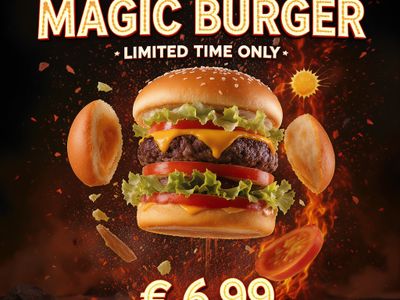
“Ad for 'Magic Burger'. Dynamic, exploded burger with all components (bun, patty, cheese, lettuce, tomato, sauce) suspended in mid-air. Emphasize photorealistic detail and a sense of motion. Dark, fiery background with glowing embers. Integrate text: 'MAGIC BURGER' as a prominent title, 'LIMITED TIME ONLY' as a secondary message, and '€6.99' in a starburst, all rendered with a fiery, glowing effect.”
“Horse riding astronaut in space — horse on top, not vice versa. Surreal, highly detailed, cinematic.”
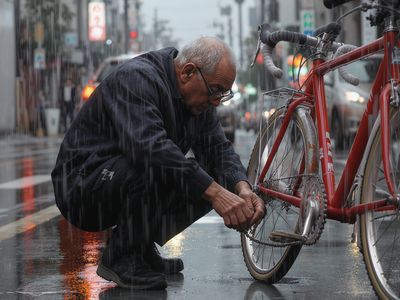
“A candid street photo of an elderly Japanese man repairing a red bicycle in light rain, reflections on wet pavement, shallow depth of field, 50mm lens, natural skin texture, imperfect framing, motion blur from passing cars, cinematic but realistic, no stylization.”
“Modern minimalist restaurant menu design, white background with colorful food photos in grid, sections for appetizers/pizza/mains, bold sans-serif fonts, vibrant accents, clean professional layout for casual dining.”
“Photorealistic scene inside a yellow New York taxi at night. A capybara is driving, wearing a yellow taxi driver cap and a dark jacket. It has a calm, professional expression and both front paws on the steering wheel. In the back seat sits a human businesswoman in a coat, looking at her phone with a completely normal, bored expression (as if this is just another normal ride). Through the windows you can see the streets of Manhattan at night with blurred lights. Realistic taxi interior, photorealistic, detailed fur and fabric, 35mm lens, night lighting with reflections, shallow depth of field.”
“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”
“Ad for 'Magic Burger'. Dynamic, exploded burger with all components (bun, patty, cheese, lettuce, tomato, sauce) suspended in mid-air. Emphasize photorealistic detail and a sense of motion. Dark, fiery background with glowing embers. Integrate text: 'MAGIC BURGER' as a prominent title, 'LIMITED TIME ONLY' as a secondary message, and '€6.99' in a starburst, all rendered with a fiery, glowing effect.”
“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”
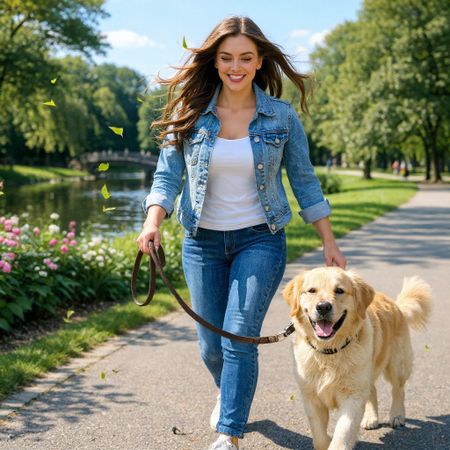
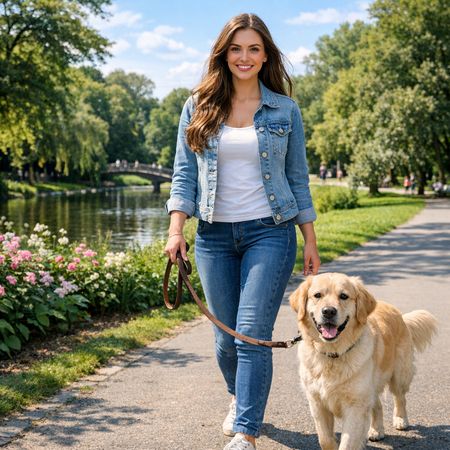
“Add dynamic motion to this photo: make hair blow in the wind, add leaves flying, energetic and lively feel.”
“Horse riding astronaut in space — horse on top, not vice versa. Surreal, highly detailed, cinematic.”
“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”
“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”
“Horse riding astronaut in space — horse on top, not vice versa. Surreal, highly detailed, cinematic.”
“A candid street photo of an elderly Japanese man repairing a red bicycle in light rain, reflections on wet pavement, shallow depth of field, 50mm lens, natural skin texture, imperfect framing, motion blur from passing cars, cinematic but realistic, no stylization.”
“Photorealistic scene inside a yellow New York taxi at night. A capybara is driving, wearing a yellow taxi driver cap and a dark jacket. It has a calm, professional expression and both front paws on the steering wheel. In the back seat sits a human businesswoman in a coat, looking at her phone with a completely normal, bored expression (as if this is just another normal ride). Through the windows you can see the streets of Manhattan at night with blurred lights. Realistic taxi interior, photorealistic, detailed fur and fabric, 35mm lens, night lighting with reflections, shallow depth of field.”
“Ad for 'Magic Burger'. Dynamic, exploded burger with all components (bun, patty, cheese, lettuce, tomato, sauce) suspended in mid-air. Emphasize photorealistic detail and a sense of motion. Dark, fiery background with glowing embers. Integrate text: 'MAGIC BURGER' as a prominent title, 'LIMITED TIME ONLY' as a secondary message, and '€6.99' in a starburst, all rendered with a fiery, glowing effect.”
“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”
“Add dynamic motion to this photo: make hair blow in the wind, add leaves flying, energetic and lively feel.”
“Modern minimalist restaurant menu design, white background with colorful food photos in grid, sections for appetizers/pizza/mains, bold sans-serif fonts, vibrant accents, clean professional layout for casual dining.”
“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”
“Ad for 'Magic Burger'. Dynamic, exploded burger with all components (bun, patty, cheese, lettuce, tomato, sauce) suspended in mid-air. Emphasize photorealistic detail and a sense of motion. Dark, fiery background with glowing embers. Integrate text: 'MAGIC BURGER' as a prominent title, 'LIMITED TIME ONLY' as a secondary message, and '€6.99' in a starburst, all rendered with a fiery, glowing effect.”
“Add dynamic motion to this photo: make hair blow in the wind, add leaves flying, energetic and lively feel.”
“Horse riding astronaut in space — horse on top, not vice versa. Surreal, highly detailed, cinematic.”
“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”
“Close portrait of a battle-worn paladin in ornate engraved plate armor, hair braided with small beads, faint scars and dirt on the skin, warm torchlight reflecting off metal, shallow depth of field, bokeh sparks, lifelike eyes, highly detailed texture on leather straps and cloth underlayer.”
“Add dynamic motion to this photo: make hair blow in the wind, add leaves flying, energetic and lively feel.”
“Modern minimalist restaurant menu design, white background with colorful food photos in grid, sections for appetizers/pizza/mains, bold sans-serif fonts, vibrant accents, clean professional layout for casual dining.”
“Ad for 'Magic Burger'. Dynamic, exploded burger with all components (bun, patty, cheese, lettuce, tomato, sauce) suspended in mid-air. Emphasize photorealistic detail and a sense of motion. Dark, fiery background with glowing embers. Integrate text: 'MAGIC BURGER' as a prominent title, 'LIMITED TIME ONLY' as a secondary message, and '€6.99' in a starburst, all rendered with a fiery, glowing effect.”
“Create a clear, 45° top-down isometric miniature 3D cartoon scene of Japan's signature dish: sushi, with soft refined textures, realistic PBR materials, gentle lighting, on a small raised diorama base with minimal garnish and plate. Solid light blue background. At top-center: 'JAPAN' in large bold text, 'SUSHI' below it, small flag icon. Perfectly centered, ultra-clean, high-clarity, square format.”
“Add dynamic motion to this photo: make hair blow in the wind, add leaves flying, energetic and lively feel.”
FLUX.1 Kontext [max] starts at $0.08 per image through Lumenfall. Pricing varies by provider. Lumenfall does not add any markup to provider pricing.
You can use FLUX.1 Kontext [max] through Lumenfall's OpenAI-compatible API. Send requests to the unified endpoint with model ID "flux.1-kontext-max". Code examples are available in Python, JavaScript, and cURL.
FLUX.1 Kontext [max] is available through fal.ai, Replicate, and Fireworks AI on Lumenfall. Lumenfall automatically routes requests to the best available provider.
FLUX.1 Kontext [max] supports images up to 2048x2048 resolution.
FLUX.1 Kontext [max] is a premium multimodal flow transformer model developed by Black Forest Labs, designed for high-fidelity text-to-image generation and complex image editing. As part of the Kontext family, it distinguishes itself by offering native support for in-context learning, allowing for precise control over character consistency and scene composition. The model is specifically engineered to bridge the gap between prompt adherence and hardware efficiency, maintaining fast inference speeds despite its high parameter count.
FLUX.1 Kontext [max] utilizes a flow matching transformer architecture, which improves upon traditional diffusion by learning a direct path between noise and the target data distribution. This approach allows for more efficient sampling and better handling of high-resolution details. The “Kontext” variant includes specific architectural adjustments to handle multi-modal inputs, enabling the model to process both text instructions and reference images within the same latent space to ensure visual consistency.
This model is best suited for professional graphic design workflows, marketing asset generation, and any application requiring precise branding like logos or posters with embedded text. It is highly effective for creators who need to generate a series of images featuring a consistent character or setting. FLUX.1 Kontext [max] is available for experimentation and production use through Lumenfall’s unified API and playground, allowing developers to integrate its advanced typography and editing capabilities into their own applications.
Generate images with custom prompts — no API key needed.